SPOT and SPOT-γ beat every drafting baseline on every task, at 2.0–3.1× the throughput of standard decoding.
Sections 5.1 and 5.2 of the paper, with Appendix F.
SDAR-8B, block 32, 256 tokens, budget 8, T = 0; three seeds, n = 350 prompts (HumanEval 164). All drafters share one decoder and verifier, so the comparison isolates drafting.
| Method | GSM8K | MBPP | HumanEval | MATH500 |
|---|
A learned commit order beats every drafting baseline on every task: 15–35% fewer passes than Spiffy's calibrated graph, at 1.1–1.5× its throughput.
SPOT-γ throughput, with the sampling distribution kept exact.
SPOT-γ throughput on MBPP at T = 1 with 512 tokens, up from 2.86× at 256.
SDAR-8B, 4B and 1.7B, LLaDA2.0-mini, LLaDA-8B and Dream-7B. The LLaDA2.0-mini checkpoint needs 3–7% more passes on SDAR-8B and still beats every baseline.
Run SPOT with the released code, in your browser or on your own GPU.
Code, drafters and a Colab notebook, by the authors.
The repository holds the decoder, the coupled-noise verifier and six trained drafters, also on Hugging Face. The Colab notebook runs SDAR-1.7B with its drafter on a free GPU.
- Install. PyTorch for your driver, then the requirements; models download on first use.
- Pick a drafter. One 0.62M-parameter checkpoint per target, in
drafters/. - Decode.
run_sweep.pyruns a task at a draft budget and logs generations, scores and acceptance.
Speed up a diffusion language model with a 0.62M-parameter drafter.
Clone, get the drafters, decode. Budget 0 is the draft-free control, run in the same call.
# 1. clone and install
git clone https://github.com/Eliezer318/SPOT-dLLM && cd SPOT-dLLM
# match the CUDA build to your driver
pip install torch --index-url https://download.pytorch.org/whl/cu124
pip install -r requirements.txt

# 2. drafters: in drafters/, also on Hugging Face
huggingface-cli download EliezerS/SPOT-dLLM --local-dir drafters

# 3. SPOT on SDAR-8B, MBPP, budgets 0 (draft-free), 8 and 20
python run_sweep.py --model sdar --block-length 32 --gen-length 256 \
  --task mbpp --limit 100 --temperature 0.0 --verify match \
  --layout concat --cache on --unmasking single --suffix skip --pad-pieces -1 \
  --draft slot --slot-mode ddtree_b --slot-ckpt drafters/sdar8b_b32.pt --slot-tokgate 0.6 \
  --budgets 0,8,20 --seeds 0 --out-root runs/sdar8b/mbpp/spot
SPOT predicts where the model commits next, then verifies a whole tree of block states in one pass.
Sections 3 and 4 of the paper, with Appendices A and C.
A block-diffusion model fills a block of masked positions over several passes, committing its most confident position each time. Each commitment changes the predictions for the rest of the block, so the model decides both what to write and where.
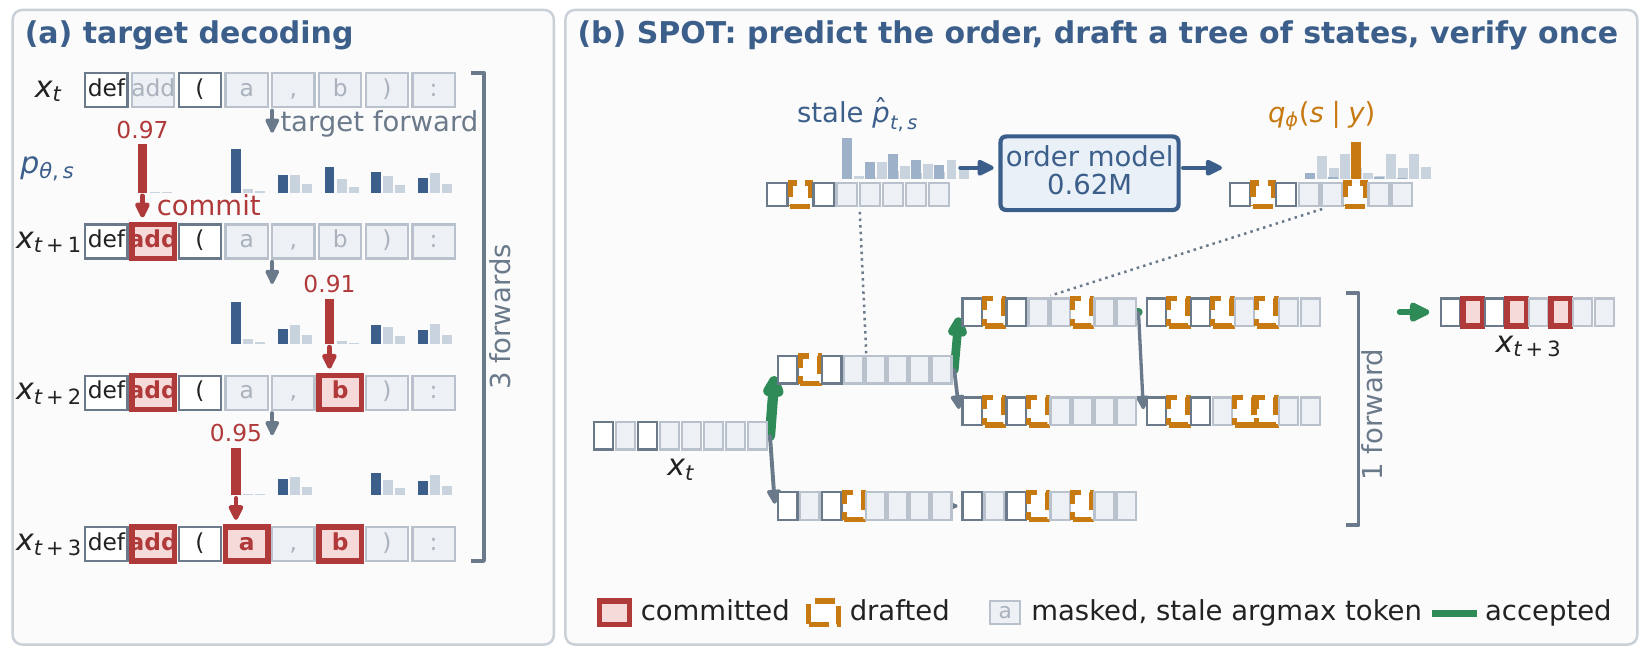
The previous pass already names the right token at 92–100% of positions, so SPOT spends its capacity on the order: it predicts the next position after each hypothetical commitment and keeps a second token candidate where the model is unsure.
Read the stale table
The top-32 distribution at each masked position, from the last pass.
Predict the order
A 0.62M-parameter model scores the next position, given the branch so far.
Grow a tree
Branches expand best first by prefix mass, up to the budget.
Verify once
One batched pass checks every state and accepts the deepest one that matches the model's own step.
Knowing the future position order is almost as good as knowing the full draft trajectory.
What makes the drafter work, and where its limits are.
Sections 3, 5.3–5.5 and 6 of the paper, with Appendices A and F.
Positions are worth more than tokens.
Oracle runs show the headroom: on GSM8K, true positions alone cut passes by 5.4× to 7.1× as the budget grows from 8 to 20, while true tokens alone give 3.3–6.5× at budget 20. SPOT predicts the next commit with 75% held-out accuracy (22% for the stale-confidence order) and recovers 70–85% of the position oracle's reduction.
Exact at any temperature.
SPOT shares per-position Gumbel noise between the drafter and the model. Given the noise, the next step is deterministic, so a whole tree is checked by equality and the sampling distribution stays exact. At T = 1, SPOT uses 15–34% fewer passes than Spiffy at 1.15–1.48× its throughput.
Branching beats a longer chain.
A chain in place of the tree is the largest loss in the ablation: on MBPP, 7.3 more passes at budget 8 and 11.9 at budget 20, with throughput at budget 20 falling from 1.72× to 1.34×.
One checkpoint, six models.
Swapped checkpoints, tokenizers included: the LLaDA2.0-mini checkpoint needs 3–7% more passes on SDAR-8B and still beats every baseline. On LLaDA-8B and Dream-7B, new to every checkpoint, SPOT cuts 256 passes to 55–88 and 51–79; both use an approximate prefix cache, so these rows show reach, and exactness is shown on the other four models.
Where the gains shrink.
Gains shrink when verification is costly or acceptance is low: at wide blocks, on low-acceptance tasks, and at T ≥ 2, where noise-aware ranking beats the order model trained at T = 0. Exact tree packing under bidirectional attention remains open.
Terms, common questions and released resources.
Condensed from Appendix H of the paper.
- Stale conditionals
- The model's latest predictions at a block's masked positions, reused for drafting with zero extra forward passes (Section 4.2).
- Commit order
- The sequence of positions the model commits, one per forward under exact decoding; the drafter predicts it as qφ(s | y) (Section 4.2).
- Draft tree
- Candidate block states grown best first from the drafter, up to a budget of D states verified in one batched forward (Section 4.2).
- Coupled-noise match
- Verification at T > 0 with the drafter and the model sharing Gumbel noise, so checking reduces to state equality (Section 4.3).
- SPOT (Speculating Positions Order Trajectory)
- The method: a 0.62M-parameter, three-layer order model predicts the next committed position, the predictions grow a draft tree, and the model verifies the tree exactly (Section 4).
- SPOT-γ
- SPOT unpadded with a prefix-mass floor γ, so the verification budget adapts to drafter confidence; γ = 0.1 on SDAR-8B (Section 4.2, Appendix D.5).
- NFE and throughput ratio
- Target forward passes per sample, and throughput relative to the draft-free run of the same task, model and temperature (Section 5.1).
What problem does SPOT solve?
Lossless acceleration of diffusion language models. A diffusion model chooses both what to write and where; SPOT drafts those choices with a small learned model, and the model verifies them in one pass (Section 1).
Why is commit order the bottleneck?
The stale prediction already matches the true token in 92% of first-block commits and ≥ 90% thereafter, while the chance that the previous round's top-confidence position commits next drops to 3% by the ninth block. Oracles show true positions are worth more than true tokens on every task (Section 3.1).
How does SPOT draft and verify?
It predicts the next committed position from the stale top-32 probabilities and repeats after each hypothetical commitment to grow a tree; the model verifies the tree in one batched forward and accepts the longest prefix that matches its own trajectory (Section 4).
Is the output exact when the model samples?
Yes, with an exact prefix cache. At T = 0 verification reproduces the draft-free trajectory for any drafter (Proposition 1); at T > 0 shared Gumbel noise gives the same distribution as draft-free decoding (Proposition 2). Draft quality affects speed alone (Section 4.3).
How does SPOT differ from Spiffy, SSD and BlockSpec?
They draft from a calibrated static graph, a confidence-ordered chain or a confidence tree; SPOT learns the commit order. Under one decoder and verifier it uses 15–35% fewer forwards than Spiffy at 1.1–1.5× its throughput on SDAR-8B (Section 5.2).
Which models and benchmarks does the paper use?
SDAR-8B (block 32) as the headline target, plus SDAR-4B, SDAR-1.7B and LLaDA2.0-mini, with transfer to LLaDA-8B and Dream-7B. Benchmarks: GSM8K, MBPP, HumanEval and MATH500; n = 350 (HumanEval 164), three seeds, 256 tokens (Section 5.1).
What are the main results?
On SDAR-8B, 3.2–4.7× fewer forwards than draft-free decoding at budget 8 (4.1–6.8× at budget 20) and 2.0–2.7× the throughput at budget 8; SPOT-γ reaches 3.23× on MBPP at T = 1 with 512 tokens. On SDAR-1.7B, where a forward is cheap, Spiffy leads three throughput columns at T = 0 and two at T = 1, with one tie (Sections 5.2–5.4).
Does SPOT work beyond SDAR-8B?
Yes, across six DLMs: the lowest NFE and highest throughput in every SDAR-4B comparison, and on LLaDA2.0-mini (a different tokenizer) the lowest NFE in all 36 comparisons and the higher throughput in 34. Transferred checkpoints also drive LLaDA-8B and Dream-7B (Section 5.4).
Where this work sits
SPOT brings speculative decoding to block-diffusion language models. It compares against self-drafting, draft-graph and confidence-tree speculation for DLMs (Gao et al., 2025; Agrawal et al., 2026; Pan et al., 2025), and verifies with Gumbel coupling (Daliri et al., 2025).